How to Structure Support Tickets for RAG Retrieval
Written by
Emil Sorensen
•
Updated
Short answer
Your resolved support tickets are probably the highest-value content you are not indexing. They contain the answers your documentation does not have, written by people who solved the problem for a real customer.
They are also the fastest way to poison a knowledge base, because a support ticket is not a document. It is a conversation with a wrong beginning, several dead ends in the middle, and sometimes a right answer at the end. Index it naively and you teach your assistant the dead ends.
The whole job is filtering. Index resolved tickets only, from the recent past, from the teams you trust, with sensitive categories excluded. Everything else is detail.
kapa.ai is an LLM-powered agentic retrieval platform purpose-built for technical sources, and it ingests support tickets as a first-class source. Specifics below are documentation of how one system does it, not a recommendation.
Why tickets are worth the trouble
Documentation describes the product as designed. Tickets describe the product as encountered.
The gap between those two is where support volume lives. A customer hits an error your docs do not mention, in a configuration your docs do not anticipate, and an engineer works out the answer in a thread. That answer now exists in exactly one place, readable by one person, searchable by almost nobody.
Three things follow.
Your best answers are already written. For a mature product, the ratio of solved problems in the ticket system to solved problems in the docs is not close. You are not creating knowledge when you index tickets, you are unlocking it.
Tickets carry the question in the customer's words. Documentation is written in the vocabulary of the people who built the thing. Tickets are written in the vocabulary of the people using it, which is the vocabulary your retrieval actually has to match.
Coverage gaps become visible. Every ticket that exists is, in some sense, a documentation failure. Once tickets and docs sit in the same index, the pattern of what people ask but cannot find gets much easier to see.
What a ticket actually contains
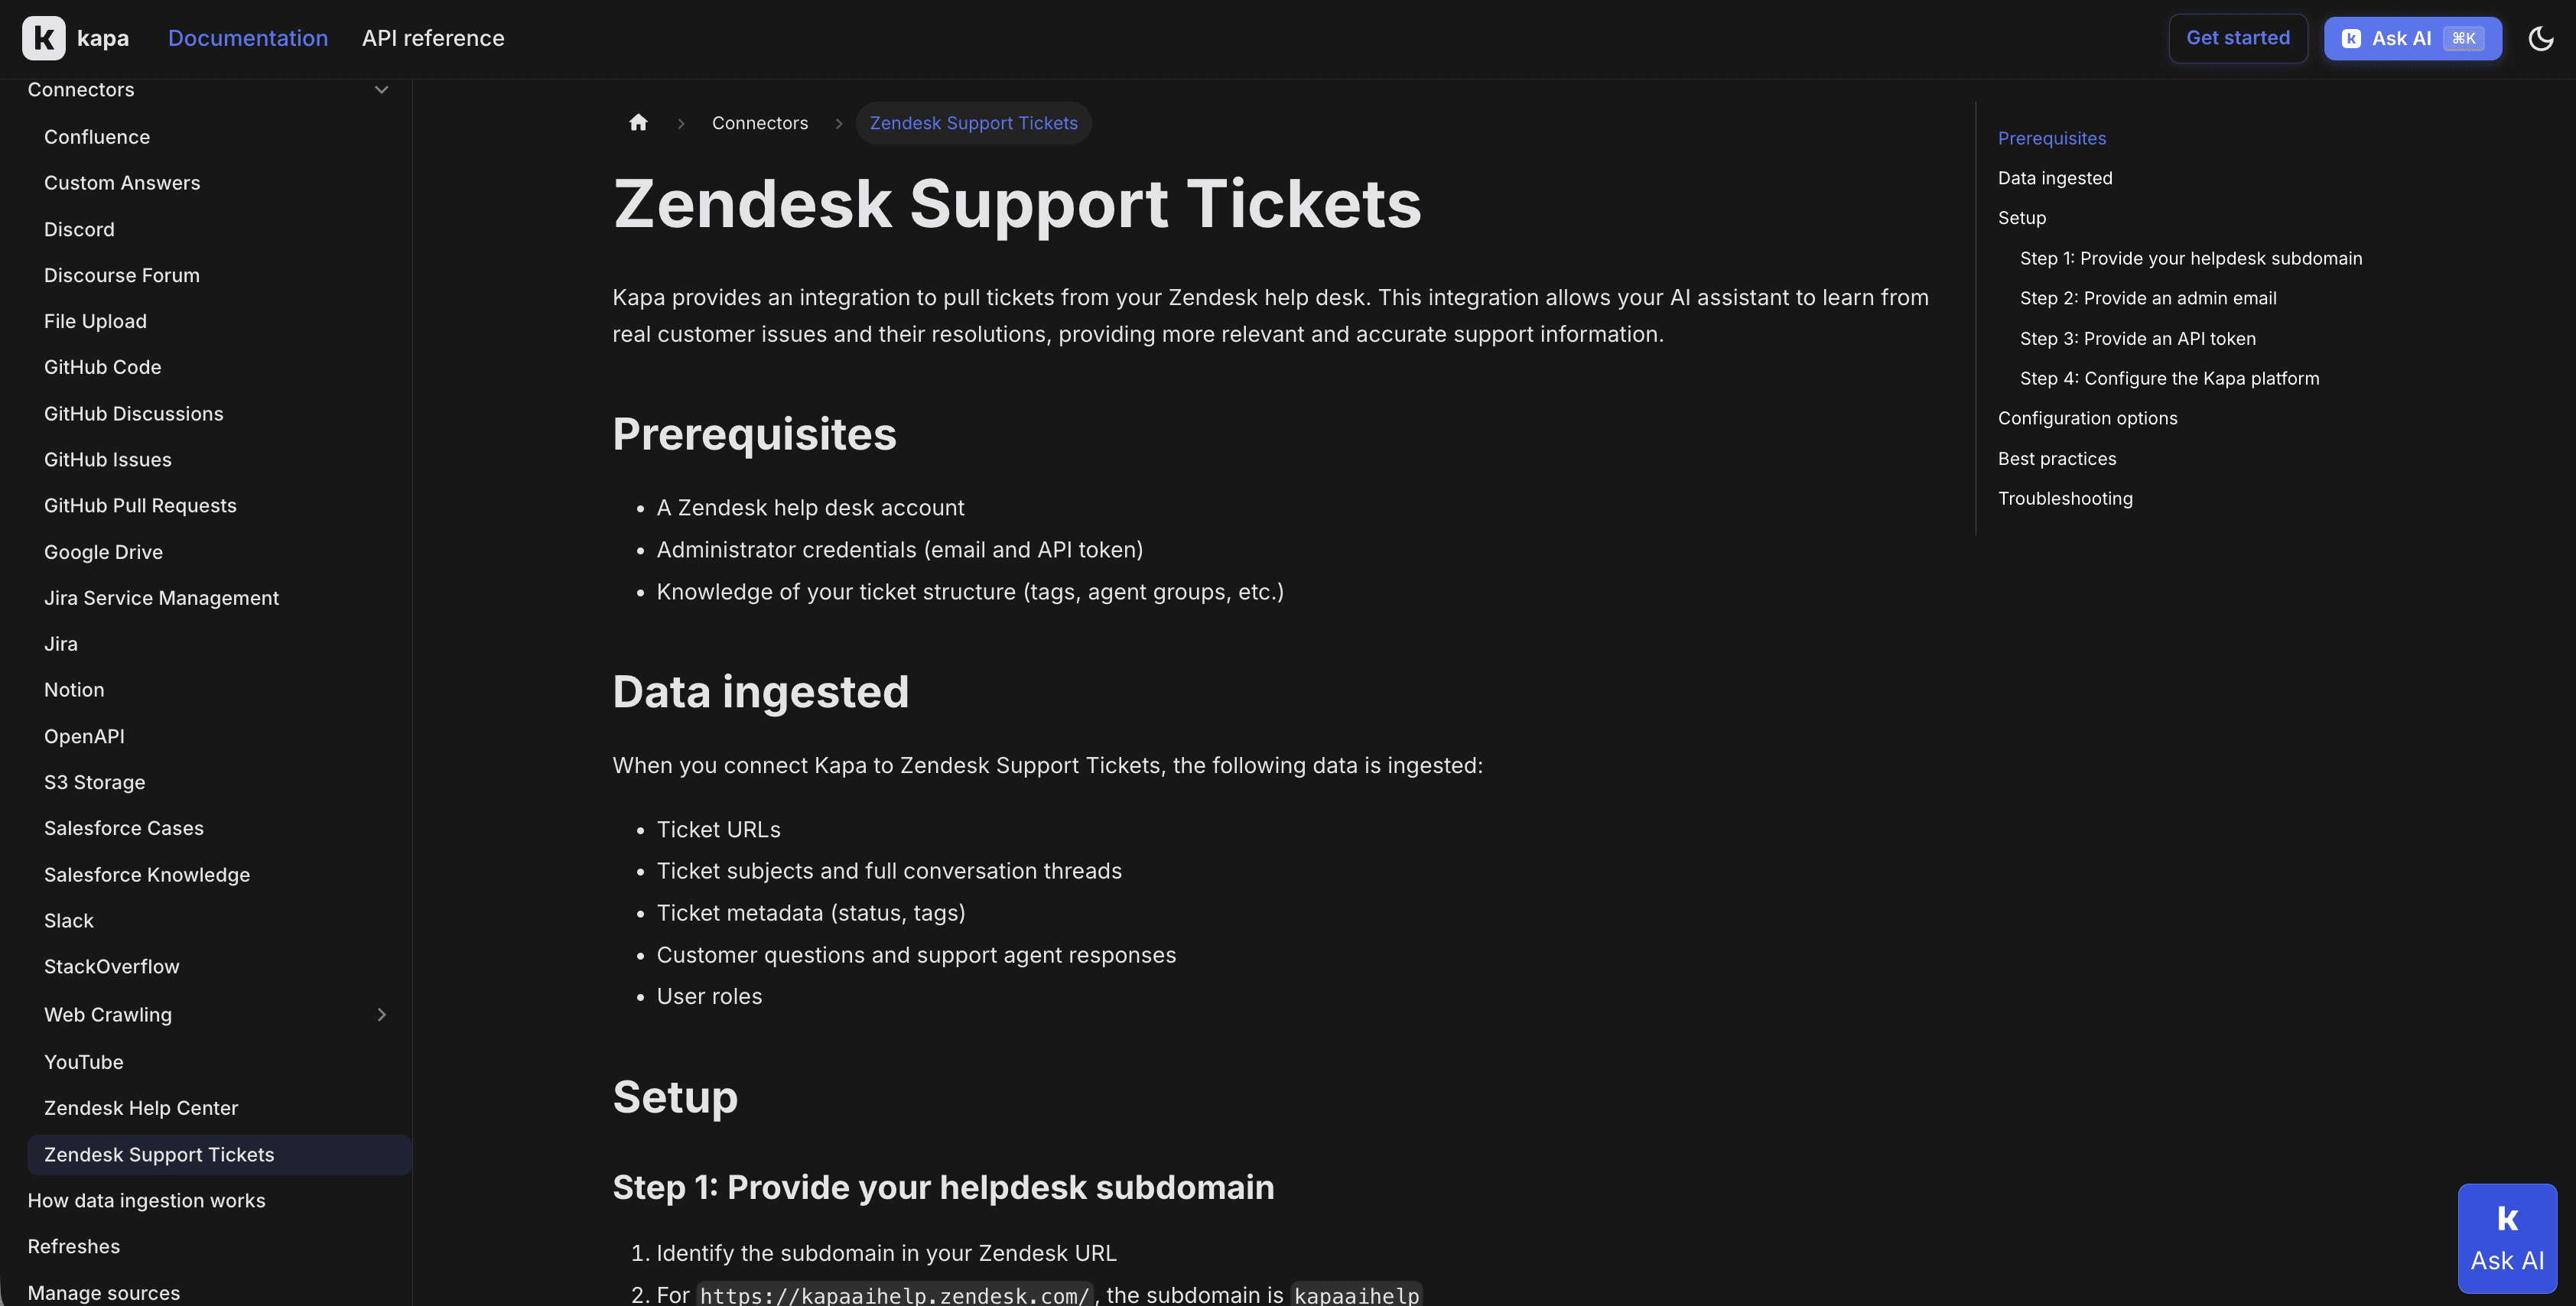
Before deciding what to index, it helps to be precise about what you are indexing. A Zendesk ticket, for example, carries a subject line, a full conversation thread of customer messages and agent replies, the role of each author, and metadata including status, priority, type, tags and the assigned agent group.
That structure matters because almost every failure mode below is a consequence of treating that bundle as one flat document.
The four ways this goes wrong
1. Unresolved tickets get treated as answers
This is the big one, and it is not subtle. A retrieval system has no concept of whether a discussion reached a conclusion. It sees text that is topically relevant to the question and returns it. If that text is an open ticket where three people are still speculating, the assistant will present the speculation as an answer.
kapa's own troubleshooting guidance is blunt about this: a system limited to answering from your ingested content has no way to know that a partial discussion is unreliable. It will surface it anyway.
The fix is upstream, not downstream. Filter by status at ingestion and index only solved and closed tickets. No amount of reranking recovers from having indexed a conversation that never concluded.
2. The first reply is usually wrong
Even in a resolved ticket, the shape of the conversation is: wrong guess, clarifying question, second wrong guess, actual answer. All of it is in the thread. All of it is topically relevant. A chunk taken from the middle of that thread reads exactly like a chunk taken from the end.
There is no clean automated fix for this, which is why the filters that follow are about raising the average quality of what you ingest rather than parsing resolution out of each thread. If your ticketing system records a solution field or a satisfaction rating, those are the most useful signals you have.
3. Resolutions go stale faster than documentation
A ticket is a snapshot of how something worked on a particular day, for a particular version. Documentation gets updated when the product changes. Tickets never do. A two-year-old resolution describing a workaround for a bug you fixed last year is not merely unhelpful, it is actively misleading, and it will keep being retrieved because it is well-written and specific.
kapa's Zendesk connector documentation recommends ingesting the last 6 to 12 months only. That is a reasonable default for most products, and the right number is a function of your release cadence rather than anything else.
4. Tickets are full of customer data
Names, email addresses, account identifiers, API keys pasted into error messages, and occasionally things that should never have been in a ticket. Documentation is written for publication. Tickets are not.
Two defences, and you want both. Exclude whole categories at ingestion using tags, so billing and account-security tickets never enter the index. Then apply PII masking to what remains, which scans content during ingestion and replaces detected personal data with anonymised labels before anything is stored.
One operational detail worth knowing: because ticket sources sync incrementally, turning on masking part-way through applies to newly ingested content. Historical content needs re-ingesting to pick up the new settings.
What to filter, concretely
For a first pass at a technical product, this is a defensible starting configuration.
Filter | Setting | Why |
|---|---|---|
Status | Solved and closed only | Excludes unresolved speculation |
Age | Last 6 to 12 months | Resolutions go stale with releases |
Type | Problem and question | Excludes tasks and internal admin |
Tags to exclude | Billing, account, security, anything sensitive | Whole categories you never want retrieved |
Agent group | Your technical support teams | Raises the average answer quality |
Start narrow. It is much easier to widen the filters after you see what retrieval does than to work out which of 40,000 indexed tickets is producing a bad answer.
How kapa handles it
This is ours, so treat it as documentation.
The Zendesk Support Tickets connector ingests ticket URLs, subjects, full conversation threads, ticket metadata including status and tags, both customer questions and agent responses, and the role of each author. Filtering is available on creation date, priority, status, type, tags to include or exclude, and agent groups to include or exclude.
The published best practices are the ones above: focus on closed tickets, consider recency and prefer the last 6 to 12 months, use tag filters to exclude sensitive categories, target tickets handled by experienced agents or carrying positive satisfaction ratings, and start with specific filters before expanding.
A few things beyond the connector matter as much.
Source groups scope what any given assistant can return. This is how one knowledge base serves a public documentation widget that never touches tickets, alongside an internal assistant that does. Without that separation, indexing tickets at all becomes a much larger decision.
Ingestion differs by source type, and a ticket is not chunked like a documentation page. How ingestion works covers the per-source machinery, including why new and updated content is picked up within minutes while deletions require a separate and more expensive pass.
Coverage gap analytics closes the loop. Questions the assistant could not answer get clustered into a backlog of documentation to write, which is the thing tickets were always telling you and nobody had time to read.
How to test whether it worked
Adding tickets should move a specific, measurable thing: the assistant's ability to answer questions whose answer is not in the documentation. Test that directly.
Find ten questions whose answer exists only in a ticket. Ask your support team, they will produce these in minutes.
Run them before you index tickets, and keep the output. Most will fail, which is the point.
Run them again after. The improvement here is the entire business case.
Run fifty questions whose answer is in the documentation, both before and after. This is the regression test, and it is the one people skip. If ticket content starts winning retrieval against your own docs on questions the docs answer well, your filters are too loose.
Include two questions about something you fixed recently, where an old ticket describes the obsolete workaround. This is how you find out whether your age filter is doing its job.
Check refusals separately from correctness. A system that answers more questions by guessing from half-finished threads will look better on a naive score and be worse in production.
Steps 4 and 5 are the ones that catch the real damage. Most evaluations only measure whether the new source helped, never whether it hurt something that already worked.
The longer version of this methodology, including how to build the test set and where LLM judges mislead you, is in how to evaluate RAG systems without relying on vibes.
The short version
Tickets are the highest-value source you can add and the easiest to get wrong. Index resolved tickets only, keep them recent, exclude sensitive categories wholesale, mask what remains, scope them away from public surfaces with source groups, and test for regressions on questions your documentation already answered.
This guide is written by kapa.ai, which makes one of the tools described. Kapa.ai is an LLM-powered RAG platform purpose-built for technical documentation, used in production by 200+ technical companies. Connector details are accurate as of September 2026.
FAQ
Should I add support tickets to my documentation AI knowledge base?
Usually yes, because resolved tickets contain answers your documentation does not have, written in the vocabulary your customers actually use. The condition is filtering. Index only solved and closed tickets from the last 6 to 12 months, exclude sensitive categories by tag, and scope them so they do not reach public surfaces unless you intend that.
How do I structure old support tickets for RAG retrieval?
Keep each ticket as one unit with its subject, conversation thread and metadata intact, rather than flattening it into loose text. Filter by status so only resolved tickets are indexed, by age so stale resolutions are excluded, and by agent group or satisfaction rating where available to raise the average quality. The structure matters less than what you choose to let in.
Why does my AI assistant answer from an unresolved ticket?
Because retrieval matches on topical relevance, not on whether a discussion reached a conclusion. An open ticket full of speculation looks identical to a solved one from the retrieval system's point of view. The fix is to filter by status at ingestion so unresolved tickets never enter the index, since no amount of reranking recovers afterwards.
How far back should I index support tickets?
Six to twelve months suits most products. Ticket resolutions describe how something worked on a particular day and for a particular version, and unlike documentation they are never updated when the product changes. The right window is set by your release cadence, so a fast-moving product should index a shorter history than a stable one.
How do I keep customer data out of an AI assistant trained on tickets?
Use two layers. Exclude whole categories at ingestion with tag filters, so billing, account and security tickets never enter the index at all. Then apply PII masking to the remainder, which scans content during ingestion and replaces detected personal data with anonymised labels before it is stored. Note that enabling masking on an incrementally synced source applies to new content, so historical tickets need re-ingesting.
Will indexing tickets make my documentation answers worse?
It can, which is why you test for it. Ticket content is specific and well-written, so it competes strongly in retrieval even on questions your documentation answers well. Run fifty questions your docs already handle correctly both before and after adding tickets, and if quality drops on those, tighten the filters rather than accepting the trade.
TRUSTED BY 200+ INDUSTRY-LEADING ENTERPRISES WITH COMPLEX PRODUCTS
- Silicon LabsAsk anything...
- LogitechAsk anything...
- n8nAsk anything...
- monday.comAsk anything...


